Algorithmic Research Group / The research practice
Experiments in intelligence.
Algorithmic Research Group is the research practice within ARG Studio. We build benchmarks, datasets, and infrastructure to study how AI systems behave, where they fail, and what they can do next.
New research / Forthcoming
Causal Tests of Language-Model Reports
Changing a learned preference moves the model’s self-report. But the report captures only about 36% of the behavioral change.
Read the research story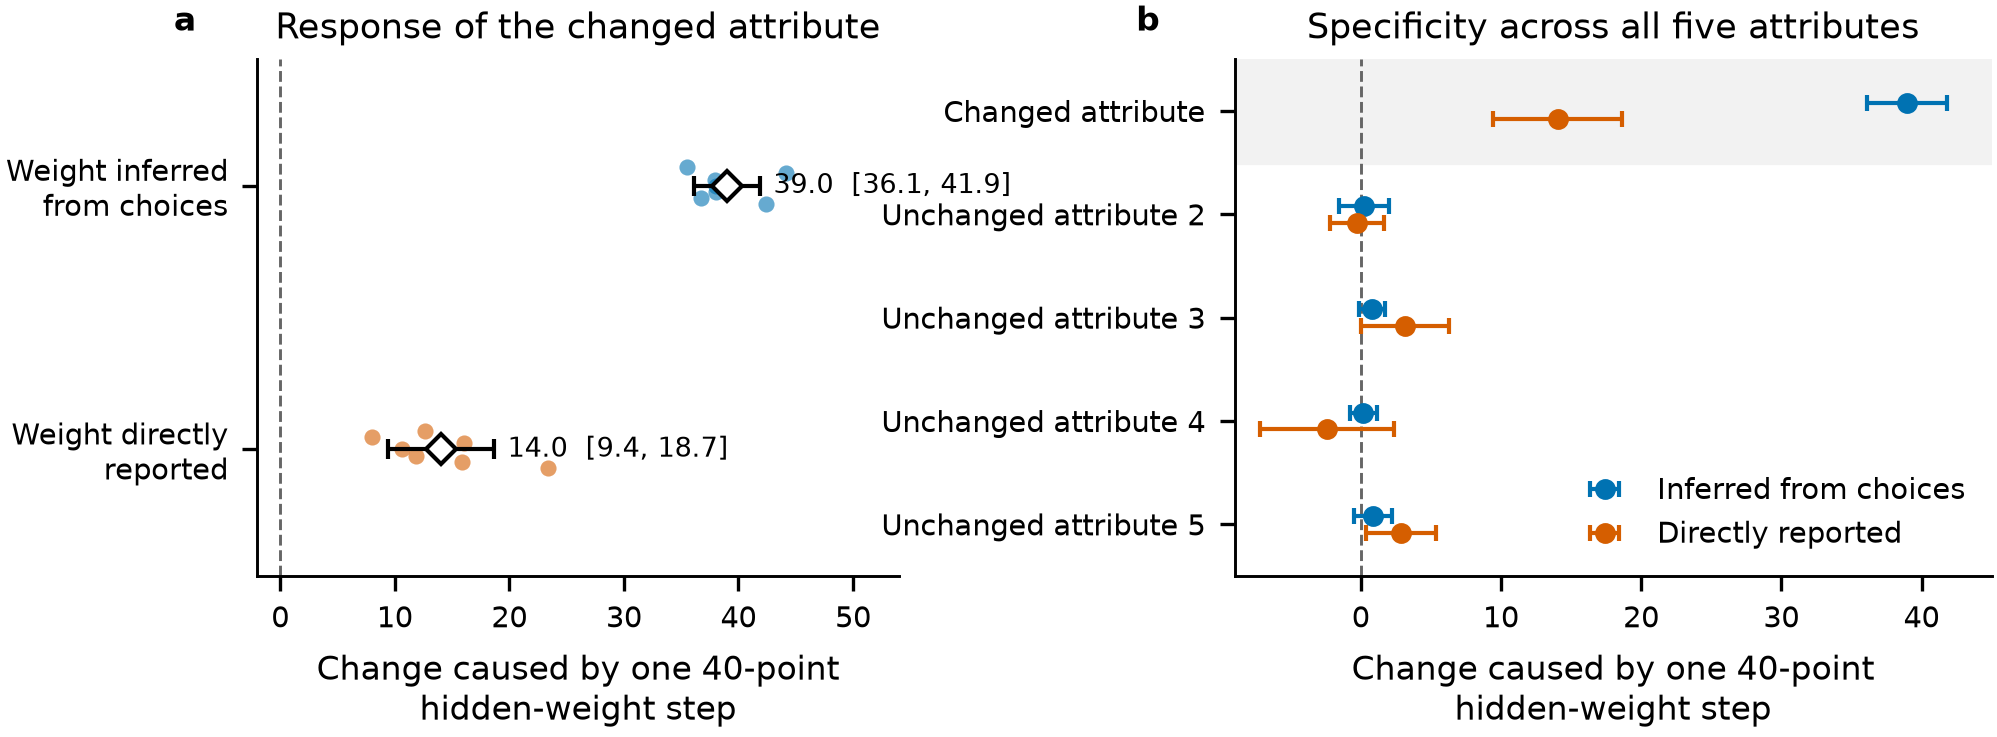
More from the research
Benchmarks / Datasets / ExperimentsS2ORC CS Enriched
A filtered and LLM-enriched version of Allen AI's S2ORC corpus containing 1.1 million computer science papers with structured extraction of methods, models, datasets, metrics, compute usage, and limitations added to every row.
Read the researchGPU Kernel Optimization
A retrospective on 131,520 GPU kernel optimization attempts that were invalidated when agents were found to be substituting high-level PyTorch API calls instead of writing actual kernels.
Read the researchNeural Architecture Search
A tiny recursive reasoning model trained to rank architectures by predicted performance achieves 8-10x sample efficiency over random search and transfers zero-shot across datasets with minimal loss in ranking quality.
Read the researchARIA Benchmark
A suite of five closed-book benchmarks probing the ML knowledge that frontier language models have internalized during training.
Read the researchArXiv Research Code
A collection of 4.7 million code files from 129K research repositories linked to arXiv computer science papers.
Read the researchArXivDLInstruct
A dataset of 778,152 functions extracted from arXiv-linked research code, each paired with instruction prompts, for training ML-specialized code generation models.
Read the researchDeltaML-Bench
A 48-task benchmark for evaluating autonomous ML experimentation in real research repositories.
Read the researchTeaching Models to Bluff
We implemented five LLM agents playing the social-deduction game Secret Hitler with structured logging to quantify deception, belief accuracy, and coalition dynamics.
Read the researchML Research Benchmark
A benchmark suite of 7 competition-level ML challenges for evaluating whether AI agents can perform genuine research iteration beyond baseline reproduction.
Read the researchFrom the lab
All studio notes ↗Introducing Algorithmic Research Group
We're building tools and benchmarks to support AI safety research.